Speaking
Speaking and Press Kit
For event organizers and journalists: bios you can copy, the topics I work on, the events I have hosted, and a headshot.
Invite me to speakBio
Three lengths. Use whichever fits your program.
One line
Ayush Ojha is a Member of Technical Staff at Wasmer in San Francisco, CA, building agent infrastructure, retrieval systems and developer tools.
Short (about 50 words)
Ayush Ojha is a Member of Technical Staff at Wasmer in San Francisco, CA, working on developer experience, SDK and runtime integration, and the AI execution sandbox roadmap. He researches evidence-grounded retrieval, agent evaluation and self-improving systems, and has hosted 50+ Bay Area events for engineers, researchers and founders, including Frontier Signals and BayForge.
Long (about 120 words)
Ayush Ojha is a Member of Technical Staff at Wasmer in San Francisco, CA, where he works on developer experience, SDK and runtime integration, and the AI execution sandbox roadmap. Before Wasmer, he built live voice agents at HiJenny, production document RAG at Tilli, and enterprise RAG and Python SDKs at Morgan Stanley. Earlier, he worked on payments at Khalti, a digital wallet platform in Nepal serving 3M+ monthly active users. His research covers evidence-grounded retrieval, agent evaluation and control, and learning and self-improvement. He has hosted 50+ Bay Area events, including the first two editions of Frontier Signals, co-hosts and MCs BayForge, and organizes through 2% Tech. He holds a first-class B.CS. (Hons) and is studying for an M.S. in Computer Science (Machine Learning) at Georgia Tech.
Speaking topics
Drawn from my current research
Evidence-grounded RAG
Source versions, retrieval scope, structured outputs, and whether answers actually use the supporting evidence. My published work examines evidence use and evaluation in controlled synthetic financial tasks, including source eligibility in question answering.
Agent evaluation and control
Explicit execution rules, reproducible cases, and failure analysis for tool-using agents. I care about separating infrastructure failures from quality failures, and about checks that run against current state before an action is taken.
Learning and self-improvement
Memory, adaptation, transfer, and feedback loops. Recursive self-improvement (RSI) is a research direction for me. My current work includes studies of memory and feedback, with proposed reinforcement-learning experiments to test what produces reliable improvements in task performance.
Hosting and community
Events I have hosted and organized
Events hosted
Attendees at Frontier Signals #01
Attendees at Frontier Signals #02
Attendees at other events and hackathons I helped organize
Series and organizations
- Frontier SignalsHost
- BayForgeCo-host and MC
- 2% TechOrganizer
Hackathons
- HackMIT 2026Mentor and judgeCompleted
- HackHarvardConfirmed engagementConfirmed
- CalHacksConfirmed engagementConfirmed
- TreeHacksConfirmed engagementConfirmed
Headshot
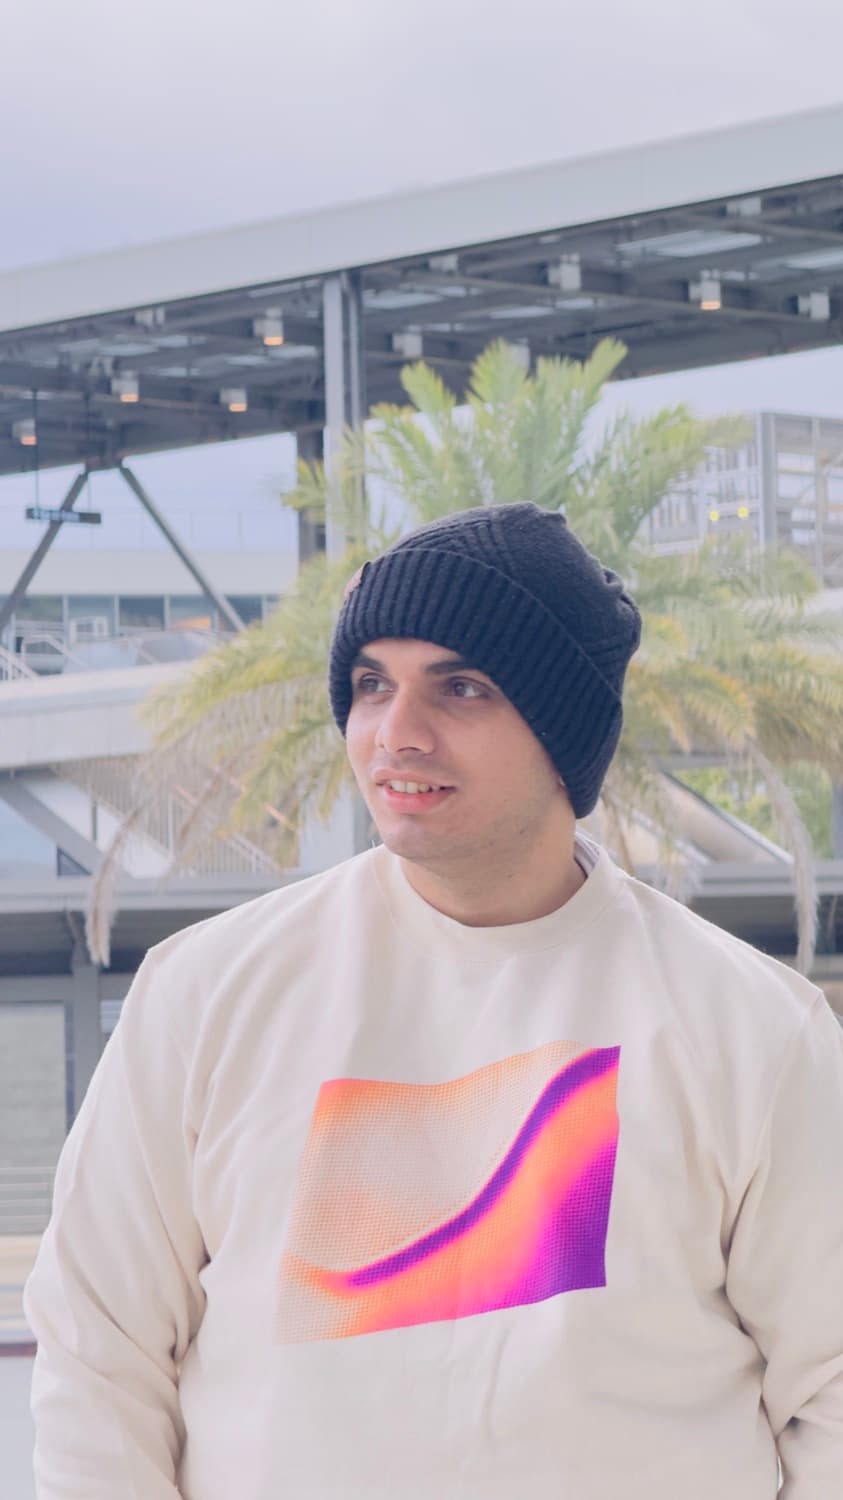
JPEG, 843 × 1500 px.
Download headshot